swale v0.2.0: GitHub, LeetCode, and an LLM you actually own
A local-first developer assistant for the terminal. This release adds GitHub sign-in, LeetCode stats, and a chat command that runs against a model on your own machine — or any provider you point it at.
npx @itssayantan/swale@itssayantan/swale on npm · source on GitHub
What it is
swale keeps the things that accumulate during a working day — a task, a thought, a receipt, a pull request, a solved problem — in one place, reachable from the terminal you already have open.
Everything lives in a single SQLite file on your machine. No account, no server, no sync, no telemetry.
v0.1.0 was todos, notes and expenses. This release is the part that makes it a developer tool rather than a notepad.
GitHub, without the ceremony
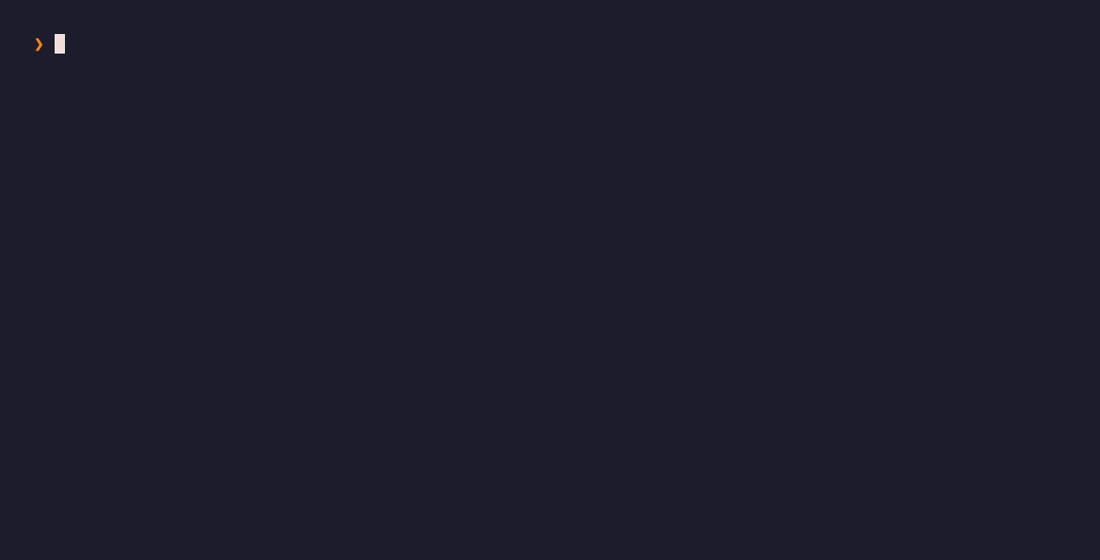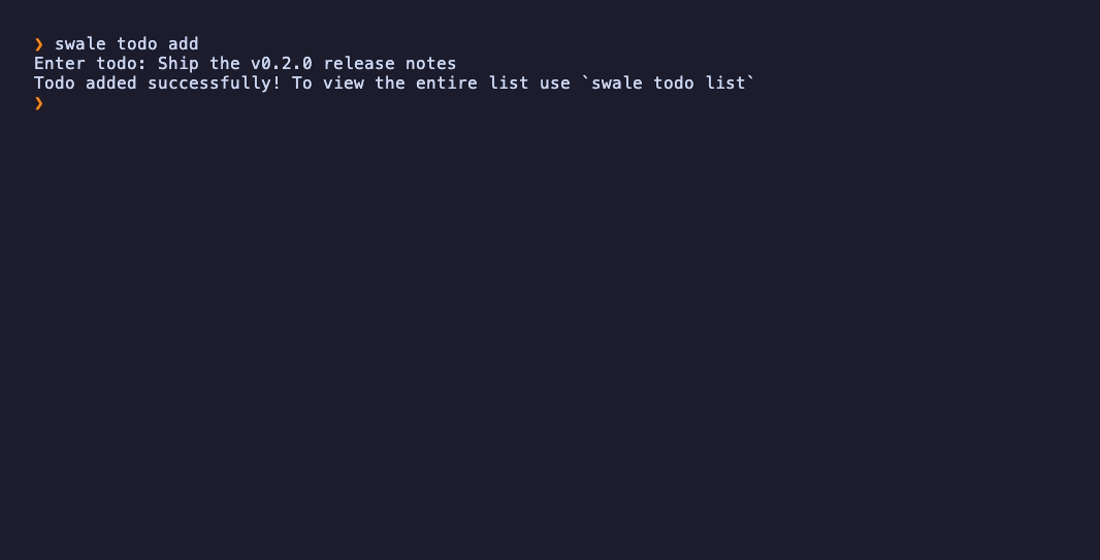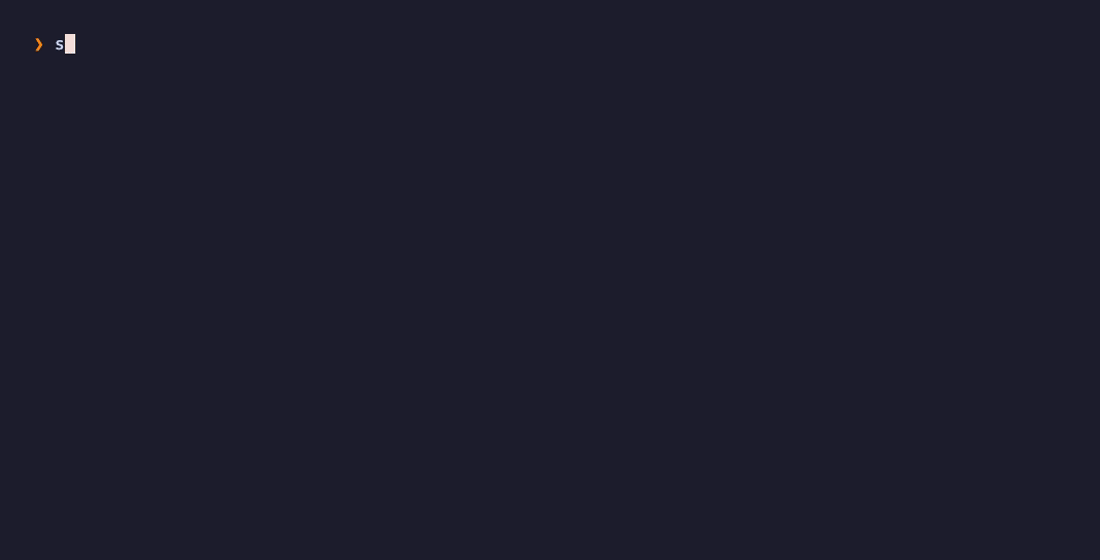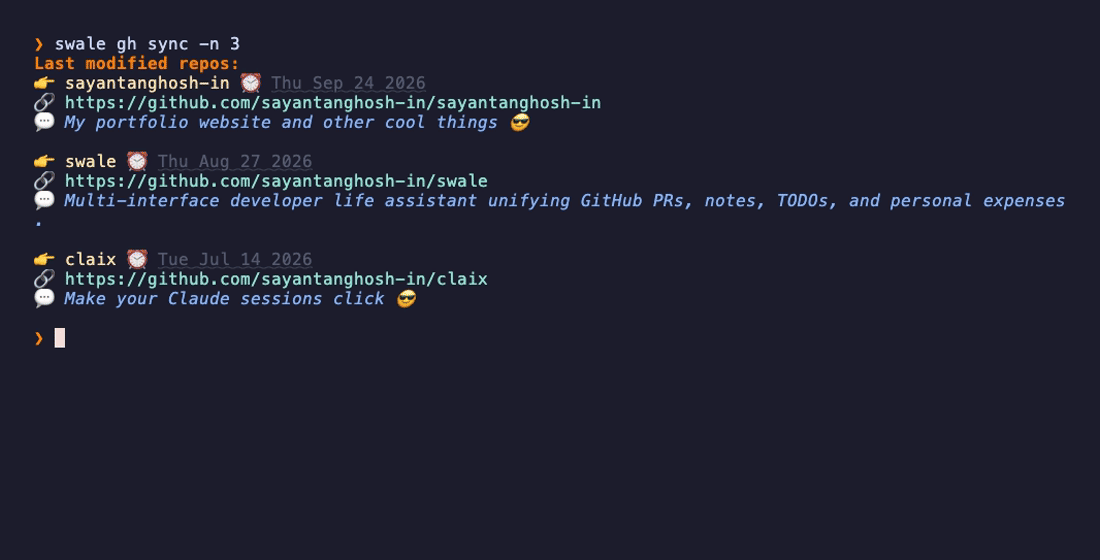
Sign-in uses the device flow — the same mechanism the gh CLI uses. You never type a password and swale never sees one.
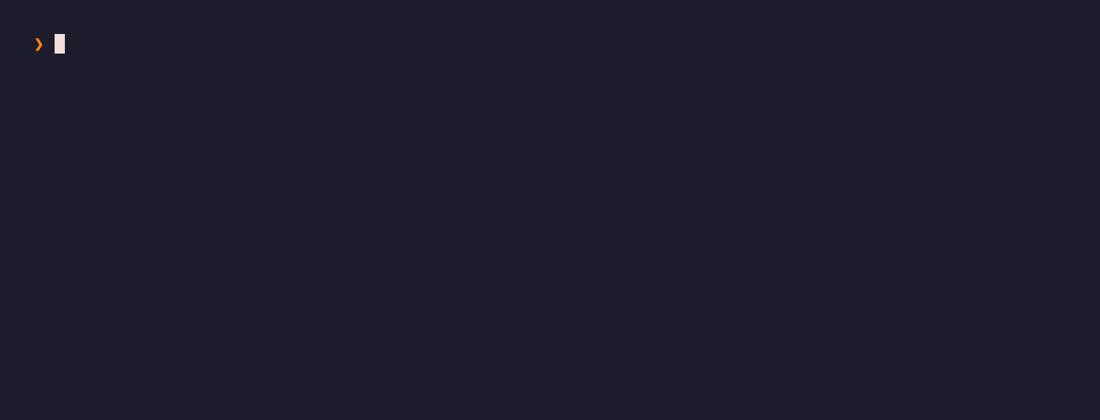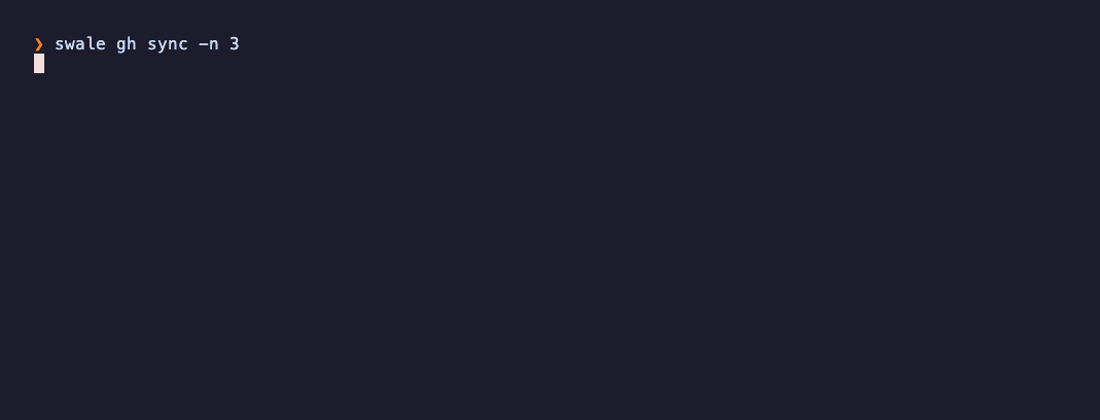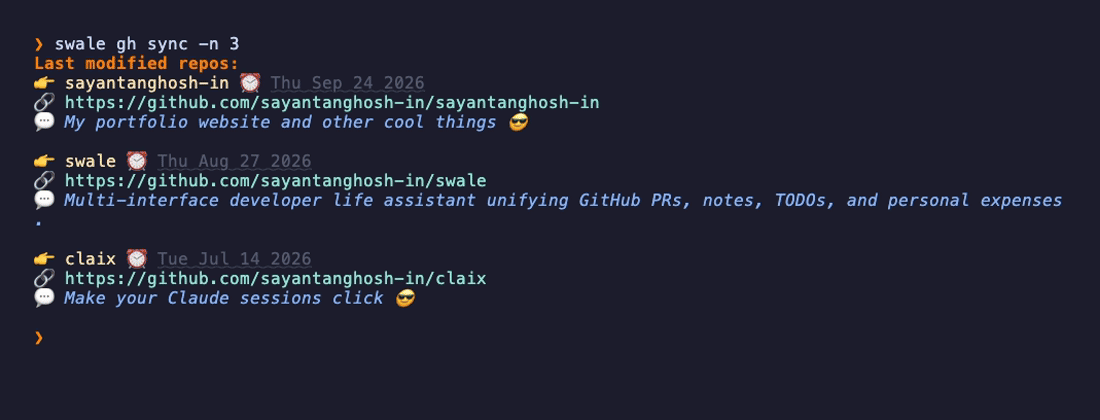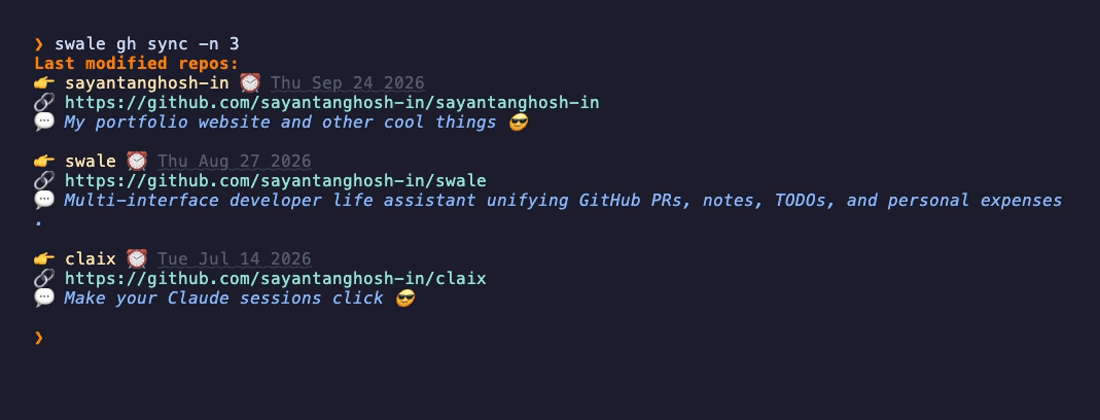
swale gh sync -n 3It asks for read:user and user:email and nothing else. It cannot write to your repositories, and private repos aren't visible to it. That's deliberate: a tool that only reads should only be able to read, and the scope screen should say so.
There is a bug worth mentioning, because it is the kind that hides well. The first version of this command hardcoded my own username into the API path. It worked perfectly for me and would have shown my repositories to every single person who installed it. The fix was to look the login up from the stored connection — but the lesson is that "works on my machine" has a sharper edge when your machine is the one in the code.
LeetCode
Username only. No credentials, no session token, just the public profile.
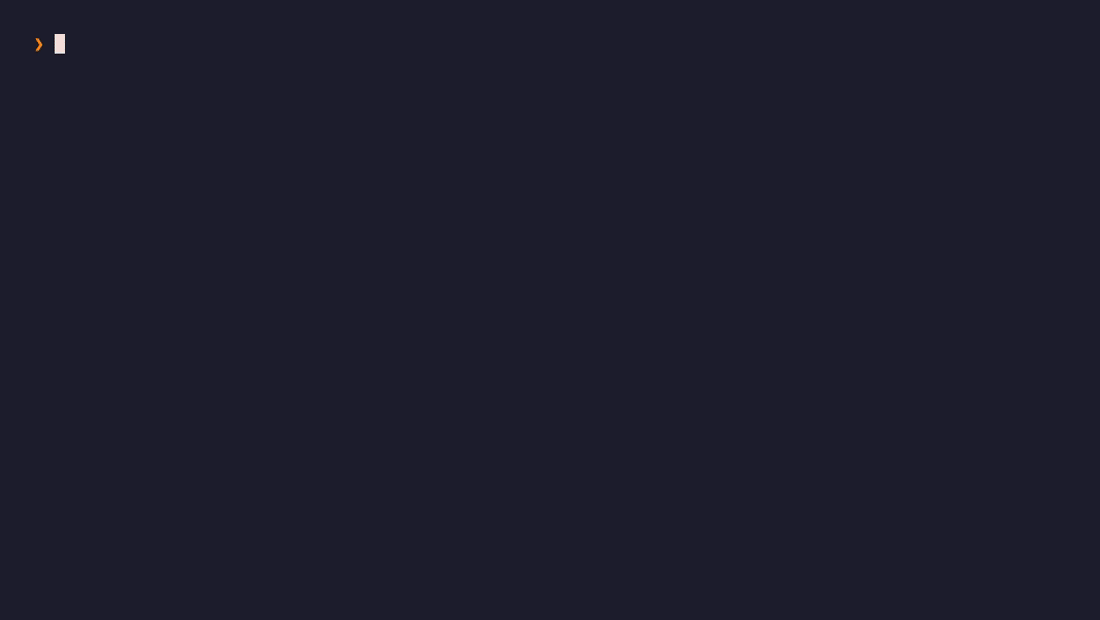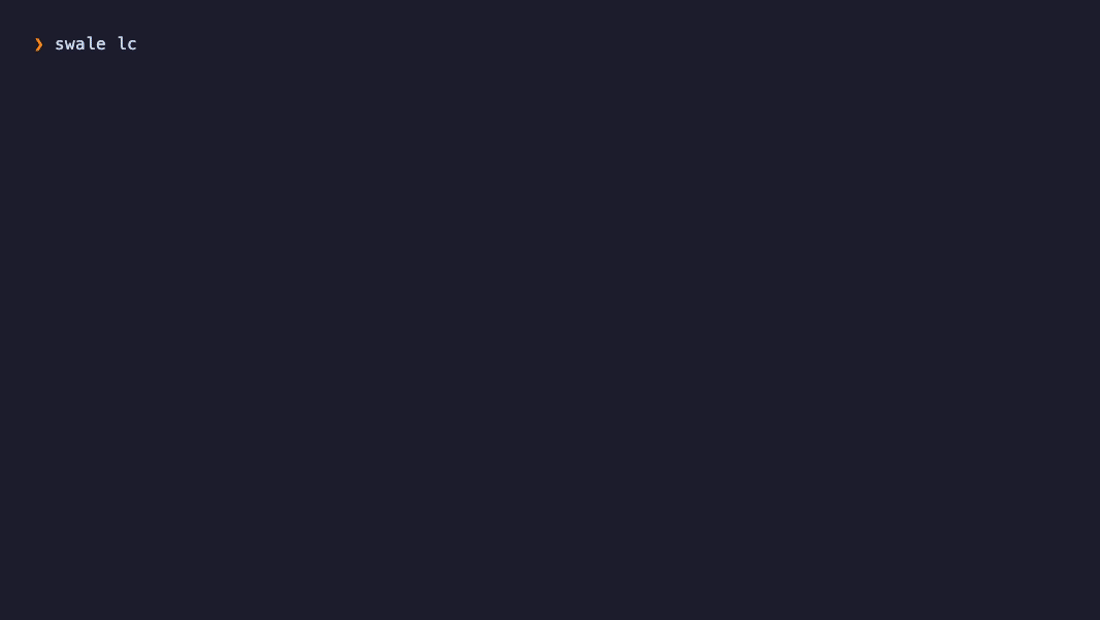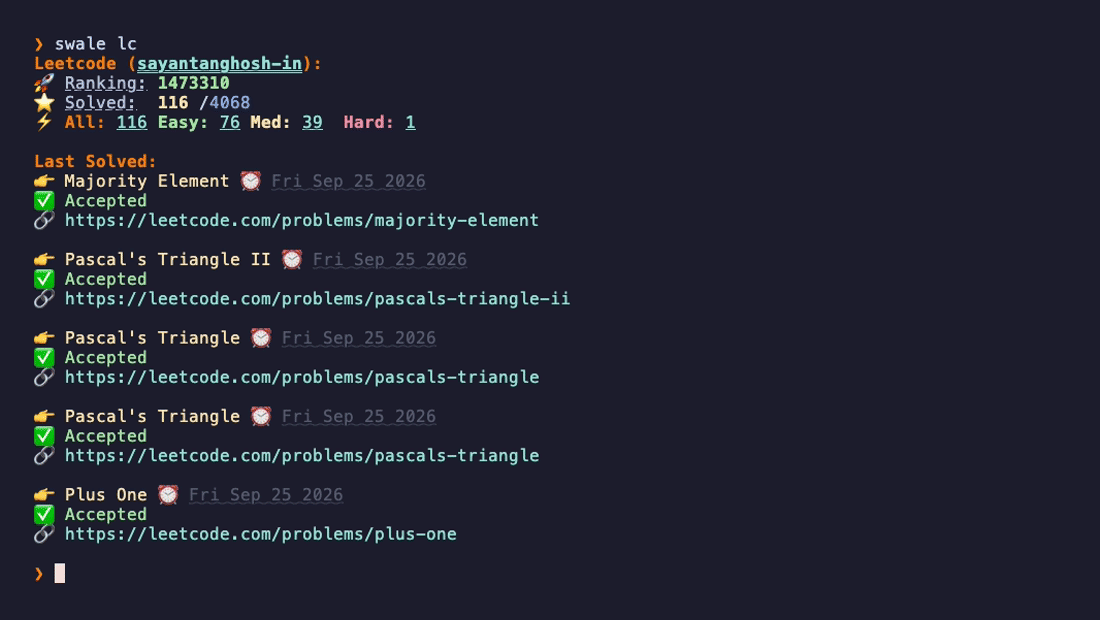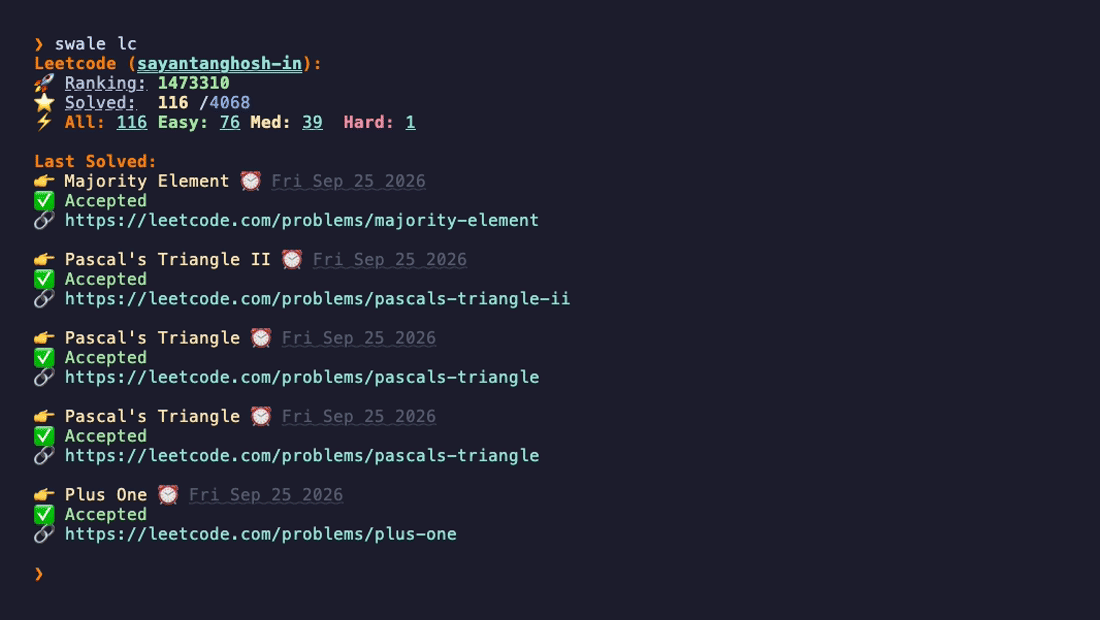
swale lc                 # the account you linked at setup
swale lc <username>      # anyone's public profile
Linking your own is optional and you can skip it during setup. I added this one because I check it most mornings and did not want a browser tab open to do it.
An LLM you actually own
This is the part I care most about.
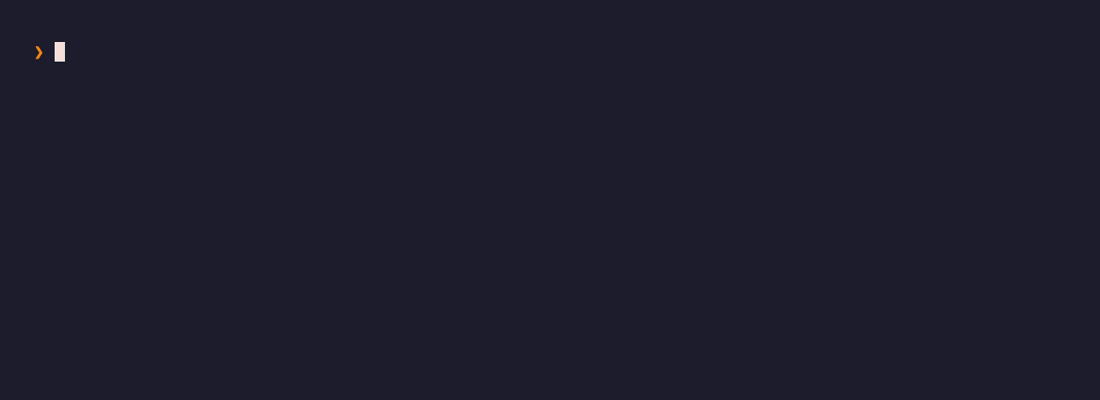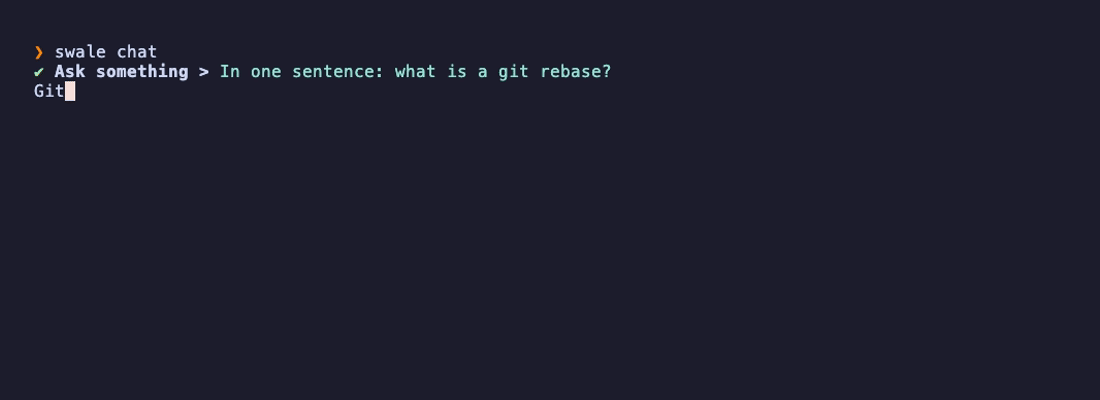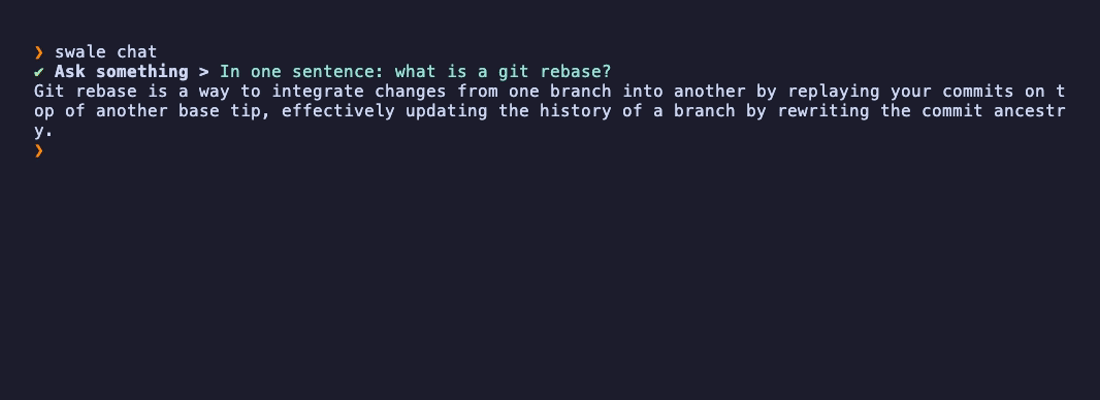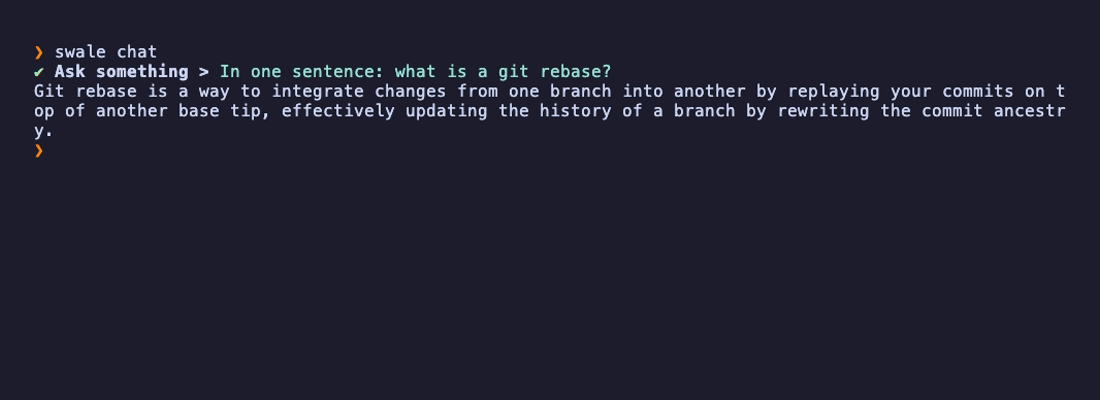
That recording is a real response from qwen2.5:7b, running locally through Ollama. Nothing left the machine, and it cost nothing.
swale llm     # connect a model
swale chat # ask it something| Type | What you give it |
|---|---|
| Local | An Ollama base URL and a model name. Defaults are sensible. |
| Remote | OpenAI, Anthropic, Groq, or anything OpenAI-compatible |
Local is the default assumption, not the fallback. That constraint has been good for the design: you cannot stuff fifty thousand tokens of context into a 7B model, so you have to think about what the model actually needs to see. You cannot rely on perfect structured output, so you validate. Every one of those is a better decision than the one you would make with a frontier model and a generous budget.
Where credentials live
Not in the database.
~/.swale/data.db        your todos, notes, expenses, profile, connections
~/.swale/config.json    GitHub token and LLM settings — 0600, never in the DB
swale has an export feature. If the token lived in data.db, every export would ship it. Keeping secrets in a separate file with restricted permissions means copying or backing up your data can never leak them.
What is next
Insights, then agents.
The next release uses the connected model to read your own data and tell you something — a morning digest, a summary of what you shipped, an answer to a question that spans more than one source.
After that, the interesting part: a tool loop. A small set of tools over the same data, and a model that decides for itself which to call and in what order. The distinction that took me longer than it should have to internalise:
A workflow is a sequence you wrote. An agent is a sequence the model wrote.
swale digest will always fetch the same things in the same order. That is a feature — it should be fast, free and predictable. But asking "what should I focus on today?" has no fixed answer path. One run might check your pull requests, notice failing CI, fetch that run's details, then look at your todos. Tomorrow it goes somewhere else, because tomorrow the data is different.
That is the part worth building, and it is why the tool surface is capped at around five parameterised tools rather than fifteen narrow ones — selection accuracy on a small local model falls off a cliff past six or so, and I would rather the thing work on your laptop than require an API key.
npx @itssayantan/swaleIt is v0.2.0 and it is early. If it breaks, open an issue — it very well might.
- Open Source
- TypeScript
- CLI
- AI
- Local-first